Spaces · Overview— / 04
Six agents. One office you can see into.
Every agent works in the open, so you can see who is doing what, who is talking to whom, and what is waiting on you.
loading the office…
Make AI inference a dependable, measurable, and governable infrastructure service.
SpacesHover near either side or drag to turn the office. Click an agent or a feature to focus on it.

Every agent works in the open, so you can see who is doing what, who is talking to whom, and what is waiting on you.

Under every agent in the office, TokenVisor runs five layers between your teams and every model. Scroll or pick a layer to see what it handles.
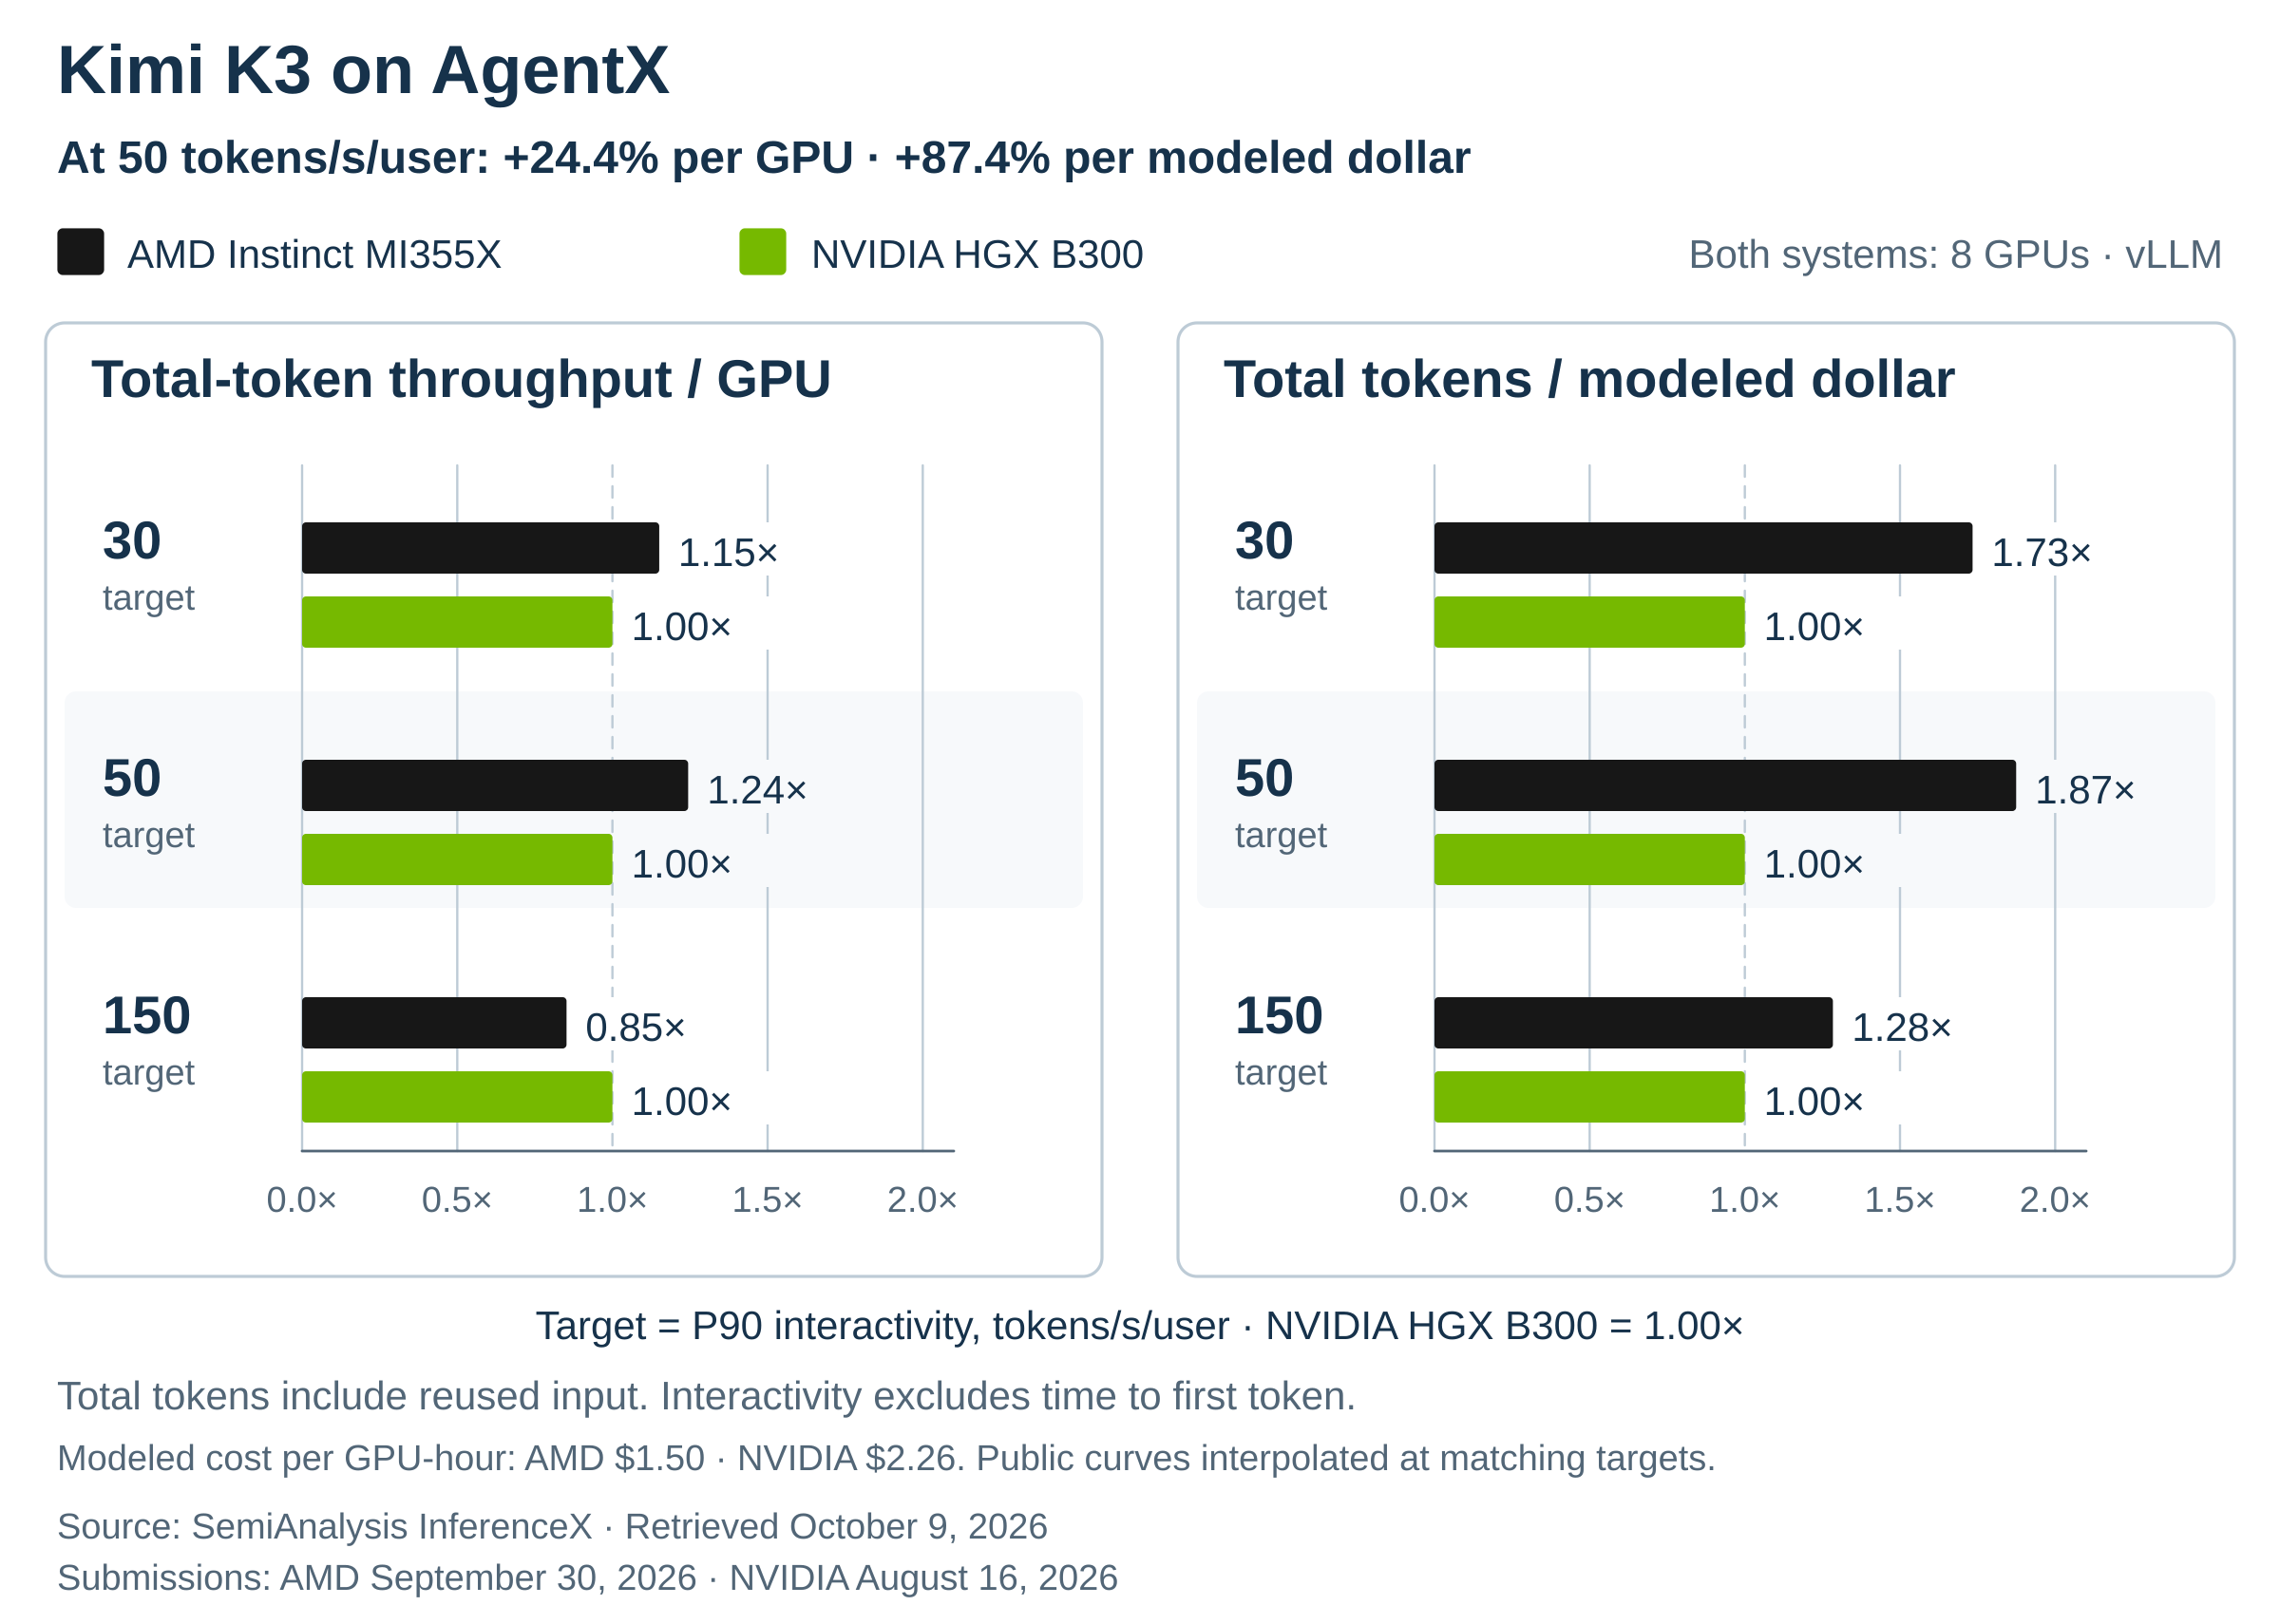
Together with AMD, Embedded LLM helped optimize Kimi K3 inference on vLLM, achieving 24.4% higher throughput per GPU and 87.4% more tokens per modeled dollar compared with NVIDIA HGX B300 at the benchmark's 50 tokens/s/user interactivity target.
Explore the engineering breakthroughs behind this result, from cache reuse and MoE optimization to speculative decoding.