The Blog
Technical deep dives, product updates, and highlights from our vLLM Meetup series. Explore the engineering insights, new features, and practical experiences shaping what we build.
Scaling Kimi K3 on AMD Instinct MI355X: A New Milestone in AI Inference Efficiency
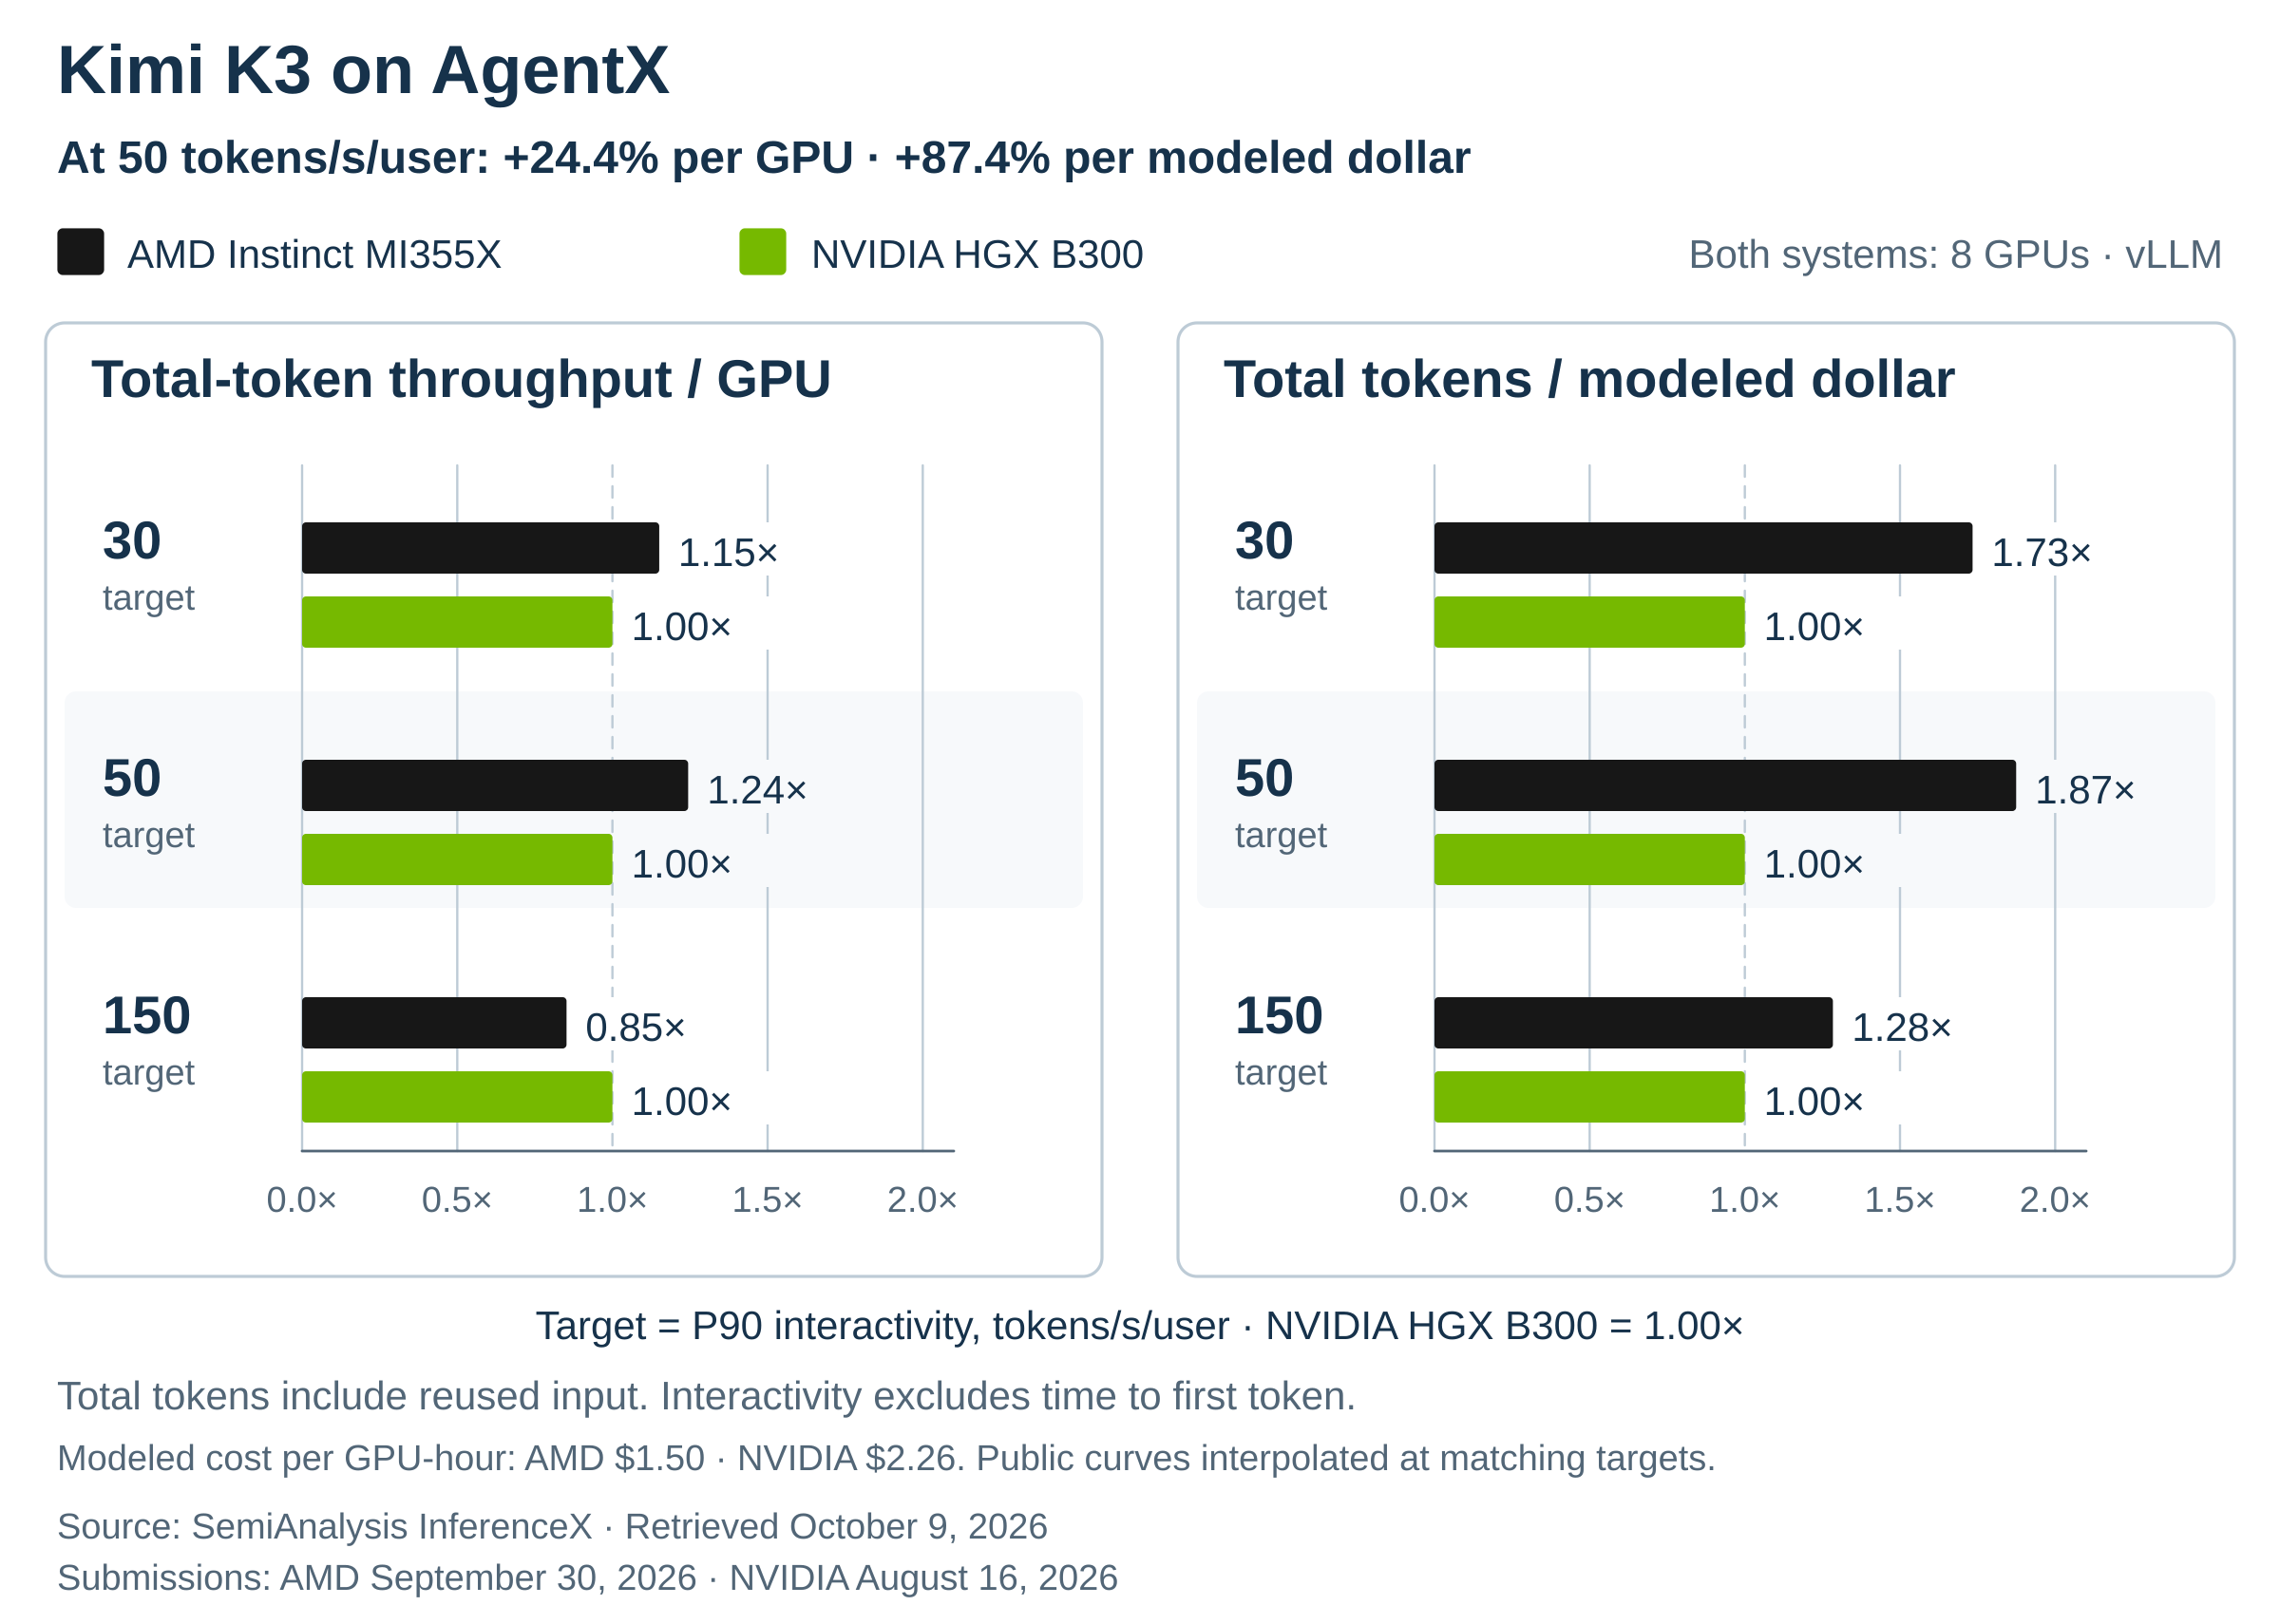
Together with AMD, Embedded LLM helped optimize Kimi K3 inference on vLLM, achieving 24.4% higher throughput per GPU and 87.4% more tokens per modeled dollar compared with NVIDIA HGX B300 at the benchmark's 50 tokens/s/user interactivity target.
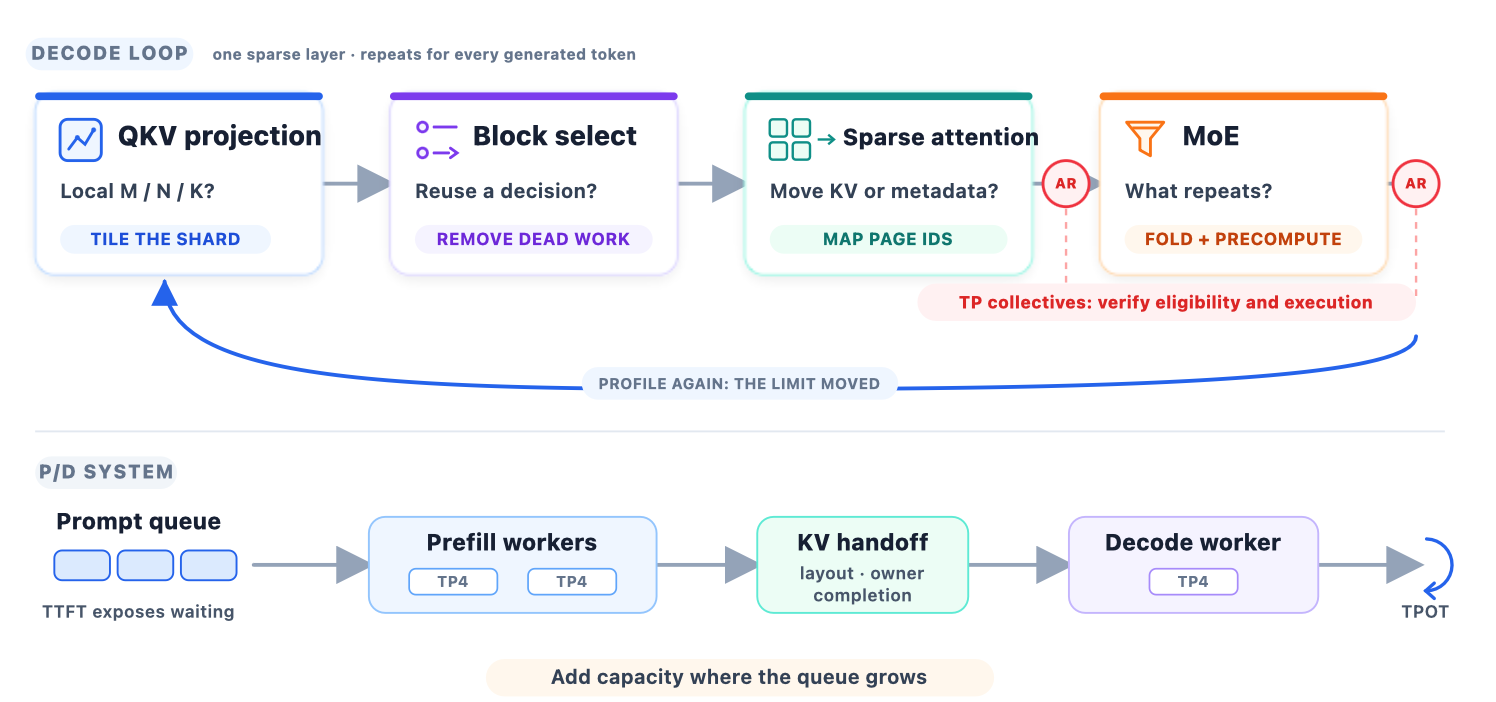
Following the Bottleneck: Optimizing MiniMax M3 on AMD Instinct MI355X
High-performance AI inference goes beyond individual kernel optimizations. By continuously identifying and addressing bottlenecks across compute, memory, and distributed systems, AMD and Embedded LLM demonstrate how software-hardware co-optimization can maximize GPU efficiency and improve production AI scalability.
External ↗ · Embedded LLM & AMD
Embedded LLM at AI Malaysia Takeover 2026: Governance, Conversations, and a Look Ahead to the Green AI Grid
A recap of AI Malaysia Takeover 2026 — governance conversations at Pasar AI, ministerial visits to the booth, and a first look at the Green AI Grid.
2 min read · EmbeddedLLM Team
vLLM Arrives in Taipei: Inside Taiwan's First vLLM Community Meet Up
A recap of the vLLM Taipei Meet Up — and the bigger announcement that followed: a new TAIONE x Embedded LLM Fellowship Track for Taiwan's vLLM community.
3 min read · EmbeddedLLM Team
vLLM Comes to Tokyo: Inside Japan's First vLLM Community Night
A recap of vLLM Community Night in Tokyo — where core contributors, AWS, Fujitsu, and Shisa.AI took the stage to talk KV cache, compression, and production inference.
3 min read · EmbeddedLLM Team
Beyond Porting: How vLLM Orchestrates High-Performance Inference on AMD ROCm
A deep dive into vLLM's 7 attention backends for AMD ROCm, featuring 1.2-4.4x throughput gains with ROCM_AITER_FA and MLA optimizations.
1 min read · Embedded LLM & AMD
Benchmarking LLM Inference on Intel Arc Pro B60: A Comparative Analysis of vLLM
A comprehensive benchmark analysis of Intel Arc Pro B60 for LLM inference workloads, comparing vLLM and LLM-Scaler performance across different scenarios.
4 min read · EmbeddedLLM Team
ROCm Becomes a First-Class Platform in the vLLM Ecosystem
Discover how vLLM 0.9.x and AITER integration deliver up to 67% throughput gains for Llama 4 and deep optimizations for DeepSeek architectures on AMD hardware.
External ↗ · EmbeddedLLM Team & AMD
Accelerating Multimodal Inference in vLLM: The One-Line Optimization for Large Multimodal Models
Unlock up to 45% higher throughput for multimodal models. Discover how vLLM's batch-level DP eliminates vision encoder bottlenecks on AMD ROCm.
External ↗ · EmbeddedLLM Team & AMD
How vLLM Built an AI Inference Community Across Asia in 2025
A recap of vLLM's four flagship 2025 community events across Singapore, Bangkok, and Malaysia — and how they built Asia's AI inference movement
5 min read · EmbeddedLLM Team
The vLLM MoE Playbook: A Practical Guide to TP, DP, PP and Expert Parallelism
The definitive guide to vLLM parallelism for MoE models. Discover exactly when to use Tensor, Data, or Expert Parallelism to scale LLMs on ROCm.
External ↗ · EmbeddedLLM Team & AMD
Stop Paying the Reload Tax: How vLLM Sleep Mode Unlocks 200x Faster Model Switching
Stop choosing between 2x VRAM costs and 100-second cold starts, free up 90% of your VRAM in seconds. Learn how vLLM Sleep Mode enables 18-200x faster model switching without the cold-start penalty.
2 min read · Embedded LLM
Introducing JamAI Base v2: From Intent to Execution
Unleash truly agentic AI with executable Python workflows, custom RAG-powered agents, and a supercharged PostgreSQL backend.
3 min read · EmbeddedLLM Team
Accelerated LLM Inference on AMD Instinct™ GPUs with vLLM 0.9.x and ROCm
Discover how vLLM 0.9.x and AITER integration deliver up to 67% throughput gains for Llama 4 and deep optimizations for DeepSeek architectures on AMD hardware.
External ↗ · EmbeddedLLM Team & AMD
Growing Solutions: Students Win FoSEAL Hackathon 2025 with AI-Powered Agriculture App
How a smart agriculture app built by students and powered by JamAI Base is reimagining the future of food security.
4 min read · EmbeddedLLM Team
Achieving BF16 Accuracy at FP8 Speeds: The PTPC-FP8 Breakthrough on AMD ROCm
When deploying Large Language Models at scale, infrastructure teams are usually forced into a painful compromise: run in full precision (BF16) and burn through expensive VRAM, or use standard FP8 quantization and watch your model's reasoning capabilities degrade.
1 min read · EmbeddedLLM Team & AMD
Beyond GPUs: Why JamAI Base Moved Embedding Models to Intel Xeon CPUs
The journey of JamAI Base towards CPU-powered embedding models highlights a crucial shift in the AI landscape. By harnessing the power of Intel Xeon CPUs and OpenVINO, JamAI Base delivers a compelling combination of performance, efficiency, and cost-effectiveness. This approach democratizes access to powerful AI capabilities, making it easier for organizations of all sizes to leverage AI for transformative outcomes
13 min read · EmbeddedLLM Team
vLLM Now Supports Running GGUF on AMD Radeon GPU
This guide shows the impact of Liger-Kernels Training Kernels on AMD MI300X. The build has been verified for ROCm 6.2.
2 min read · EmbeddedLLM Team
Liger Kernels Leap the CUDA Moat: A Case Study with Liger, LinkedIn's SOTA Training Kernels on AMD GPU
This guide shows the impact of Liger-Kernels Training Kernels on AMD MI300X. The build has been verified for ROCm 6.2.
8 min read · EmbeddedLLM Team
See the Power of Llama 3.2 Vision on AMD MI300X
This blog post shows you how to run Meta's powerful Llama 3.2-90B-Vision-Instruct model on an AMD MI300X GPU using vLLM. We provide the Docker commands, code snippets, and a video demo to help you get started with image-based prompts and experience impressive performance
5 min read · EmbeddedLLM Team
Serving Llama 3.1 on AMD MI300X: How vLLM Crushes TGI Benchmarks
Unlock up to 1.8x higher throughput and 5.1x faster TTFT on AMD MI300X. Discover the 8 optimized vLLM settings for serving Llama 3.1.
1 min read · Embedded LLM
How to Build vLLM on MI300X from Source
This guide walks you through the process of building vLLM from source on AMD MI300X. The build has been verified for ROCm 6.2.
7 min read · EmbeddedLLM Team
High throughput LLM inference with vLLM and AMD: Achieving LLM inference parity with Nvidia
EmbeddedLLM has ported vLLM to ROCm 5.6, and we are excited to report that LLM inference has achieved parity with Nvidia A100 using AMD MI210.
7 min read · EmbeddedLLM Team